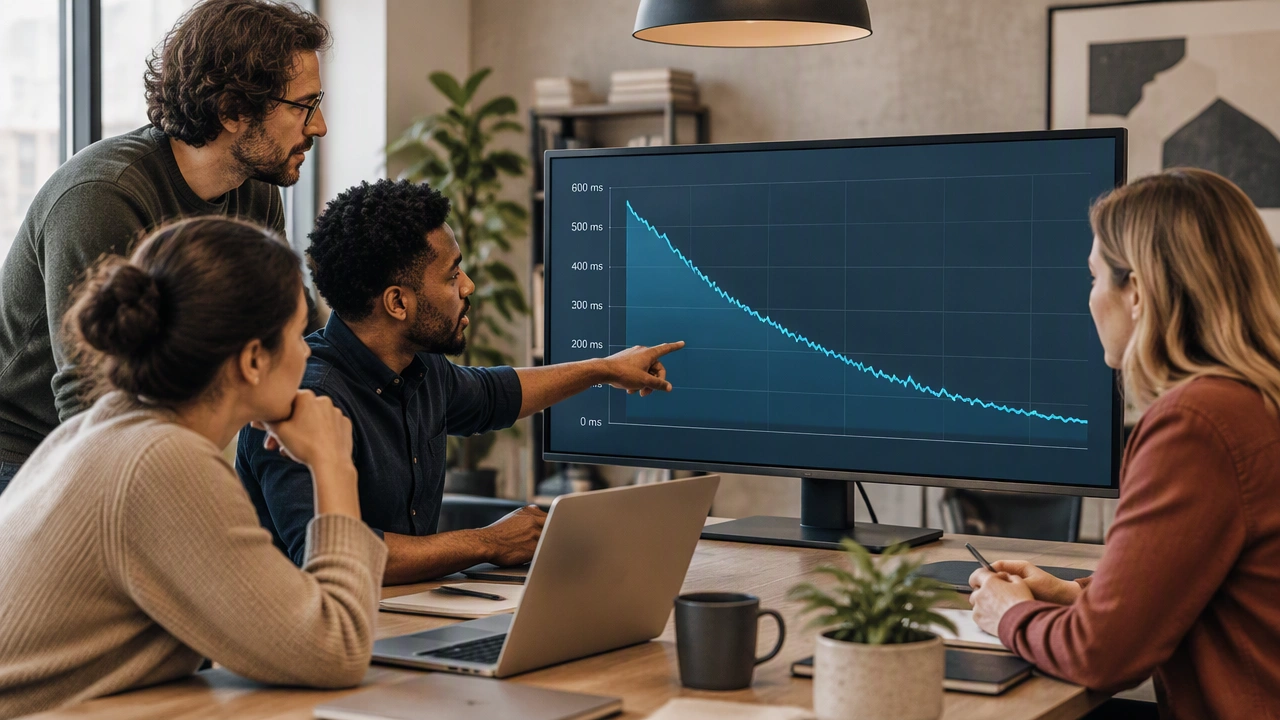
This case study details how our team tackled a critical API performance problem serving over ten million requests daily. Users were experiencing p99 latencies above two seconds, leading to timeouts and customer complaints. We started by instrumenting every endpoint with distributed tracing using OpenTelemetry. The data revealed that 60 percent of latency came from three expensive database queries and unnecessary serialization overhead. We introduced read replicas for heavy queries, implemented response caching with a five-minute TTL for stable endpoints, and switched from synchronous JSON serialization to Protocol Buffers for internal services. Database connection pooling was tuned to reduce context switching. Within three weeks, p99 latency dropped from 2.1 seconds to 600 milliseconds. This topic shares the full journey including false starts and lessons learned.