Speed Up Data Access with Query Plans and Indexes
Software speed often depends on the database. A screen may render quickly, but users still wait when a report scans millions of rows or a checkout path performs the same lookup repeatedly. This guide explains how to tune slow database queries by reading query plans, choosing useful indexes, and measuring results without introducing new risks.
Start with a clear performance target
Before changing SQL, define what improvement means. Record the current response time at a realistic data size, note how often the query runs, and identify the part users experience. A query that runs once per night has different constraints from one used on every page view.
Collect a small baseline:
- Latency: average and high-percentile duration under normal load.
- Frequency: calls per minute, per user, or per transaction.
- Rows examined: how much data the engine reads to return the result.
- Resource use: CPU, memory, disk reads, and lock waits.
Keep the measurement window consistent. Compare the same dataset, hardware, and concurrency level so later changes are meaningful.
Read the query plan before changing the query
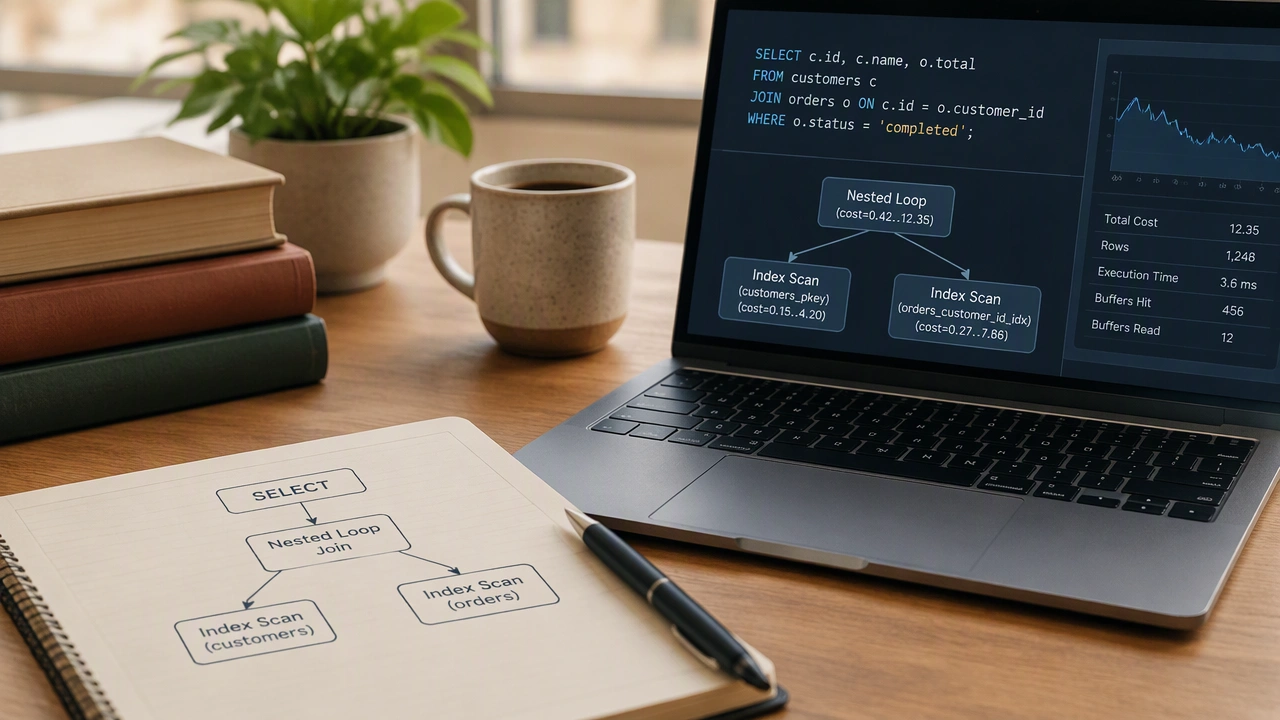
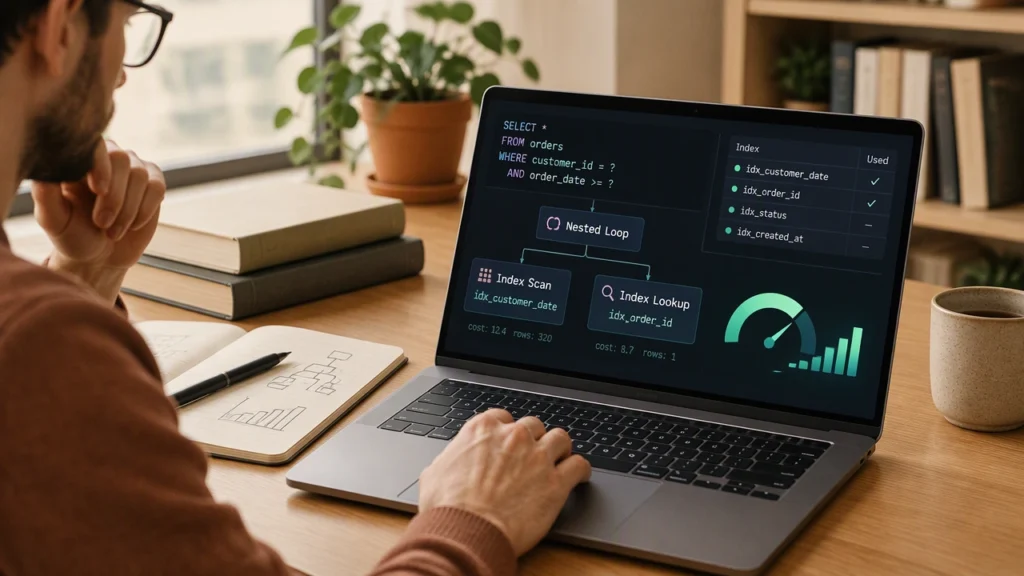
A query plan is the database optimizer’s explanation of how it will execute a statement. Plans vary by engine, but most show the same basic ideas: access method, join order, estimated rows, and actual work performed.
Look for these signals:
- Full scans: the engine reads an entire table instead of a narrow range.
- Large row estimates: estimates far from actual values suggest stale statistics or misleading expressions.
- Expensive joins: nested loops over large inputs often indicate a missing index or a poor join order.
- Sorts and spilling: sorting large intermediate results can force temporary disk work.
- Repeated work: the same subquery or function may run for every row.
Capture both the estimated plan and, when available, an actual plan with runtime row counts. The difference between estimate and reality is often the most useful clue.
Match indexes to real access paths
An index is a separate structure that lets the engine locate rows without scanning a whole table. The best index follows the way the application actually reads data.
Start with predicates that filter or sort frequently. A composite index usually works best when its columns follow this pattern: equality columns first, then the column used for range filtering or ordering. For example, a query that filters by status and sorts by created time may benefit from an index on status and created_at.
Keep these limits in mind:
- Leading-column rule: most engines can use the leftmost columns of a composite index first.
- Selectivity: a column with many duplicate values may need a second column to be useful.
- Write cost: every index adds maintenance work to inserts, updates, and deletes.
- Function expressions: if a query applies a function to a column, consider an expression index or rewrite the predicate.
Do not add indexes by intuition alone. Confirm with the plan that the engine chooses the new path and that the estimated rows drop to a reasonable range.
Improve the SQL around the plan
Indexes are not a substitute for clear, selective SQL. Small changes often remove hidden work.
Select only needed columns. Avoid SELECT * when the caller uses a few fields. Wide rows increase memory use and may prevent covering-index access.
Filter early. Move conditions into the innermost query so the engine can reduce rows before joins or grouping. Make sure the logic remains correct when predicates involve nullable columns.
Limit expensive operations. Pagination with OFFSET can skip many rows on deep pages. Keyset pagination, using the last seen sort value, keeps work proportional to the page size.
Watch for implicit conversions. Comparing a text column to a number, or using a different collation, can disable an index. Keep parameter types aligned with column types.
Reduce N+1 patterns. Repeated single-row lookups from application code can overwhelm a fast query. Batch requests or use one set-based statement when the data model allows it.
Validate changes with controlled experiments
Change one thing at a time. Run the query again with the same plan capture method and compare rows read, execution time, and resource use. Test with production-like cardinality; an index that looks perfect on ten rows may behave differently on ten million.
Check for side effects:
- Write latency and storage growth after adding indexes.
- Lock contention during heavy updates.
- Plan stability when parameters change.
- Behavior under concurrent load, not only in a single session.
If a query improves but the overall screen does not, inspect the surrounding steps. Network calls, serialization, and repeated queries can dominate the total time.
Make tuning a routine
Database performance changes as data grows and access patterns evolve. Keep a short list of critical queries, record their baseline plans, and review them after major releases or large data migrations. Refresh statistics regularly and watch for plans that switch unexpectedly.
A calm, repeatable process works better than dramatic rewrites: measure, read the plan, add the smallest useful index, simplify the SQL, then verify the result. That rhythm turns database tuning into a predictable part of software delivery rather than an emergency response.