Async Queues and Background Jobs: Smoothing Bursts to Improve Throughput
Software speed is not only about making individual operations faster. It also depends on how a system handles bursts. When many tasks arrive at once, synchronous processing can create long response times, cascading timeouts, and unstable behavior. Queues and background jobs are a practical way to absorb those spikes, spread work over time, and keep throughput consistent even under pressure.
This approach is especially valuable when you want to improve throughput with background queues while preserving reliability and user experience. Instead of doing all work inline, you separate what must be immediate from what can be deferred, then process the deferred work in a controlled, scalable way.
Why queues smooth bursts
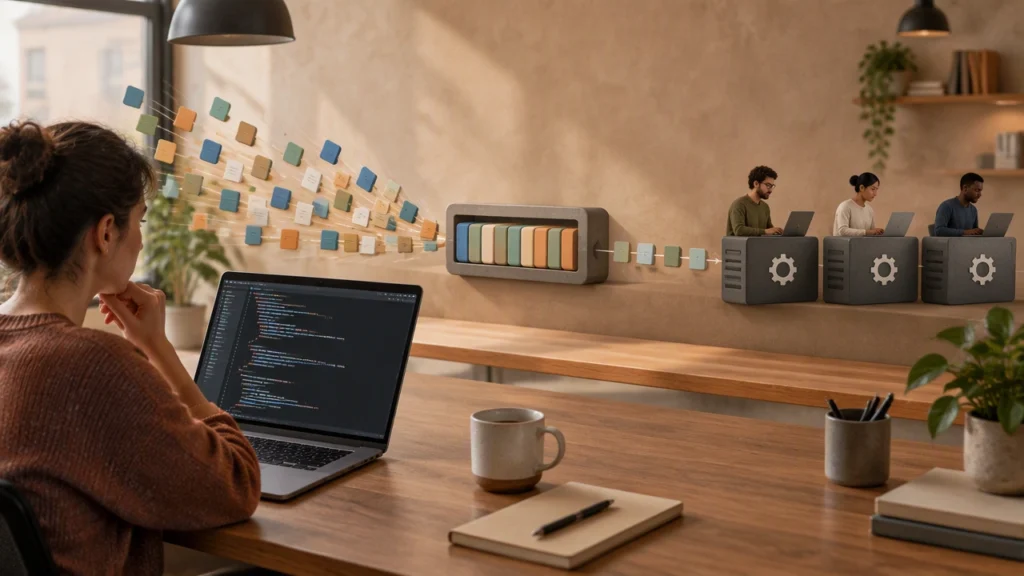
A queue introduces a simple but powerful idea: decouple the moment a task is requested from the moment it is executed. The application accepts the work, places it in a durable queue, and returns quickly. Background workers then pull tasks from the queue and run them at a pace the system can sustain.
This model helps because it turns unpredictable spikes into a steadier stream of work. It also makes capacity easier to manage. Instead of provisioning for every peak moment, you can scale workers based on backlog size, processing time, and target latency.
Common examples include sending emails, generating reports, processing uploads, calling slow third-party APIs, running billing calculations, and building search indexes. In each case, the user does not need to wait for the full task to finish.
When to move work to the background
Not every task belongs in a background job. A good rule is to move work to the background when any of the following are true:
- The task is slow, resource-heavy, or likely to vary in duration.
- The task calls an external service with unpredictable latency.
- The task can be retried safely without affecting correctness.
- The result can be delivered later through a status update, notification, or export.
- The burst rate is much higher than the sustainable processing rate.
On the other hand, operations that must be immediate and consistent with the user action, such as confirming a payment or writing a critical record, are usually better kept synchronous or handled with careful transaction design.
A simple queue architecture
A basic but effective setup includes four parts:
- Producer: The service that creates tasks and pushes them to the queue.
- Queue broker: The system that stores tasks durably and delivers them to workers.
- Workers: Background processes that pull tasks, execute them, and report results.
- Monitoring: Metrics and alerts for backlog depth, processing time, failures, and retries.
Many teams start with a managed broker such as Amazon SQS, Google Cloud Tasks, or Azure Service Bus. Others use open-source options like RabbitMQ, Redis Streams, or Kafka. The right choice depends on durability needs, delivery guarantees, operational budget, and ecosystem fit.
Patterns that improve throughput
Backpressure and rate limiting
Throughput improves when the system protects itself from overload. Backpressure ensures workers do not take more than they can finish. Rate limiting controls how fast tasks are produced or consumed. Together, they keep latency predictable and prevent resource exhaustion.
Batching
Some tasks can be grouped and executed together. Batching reduces per-task overhead and makes better use of connections, memory, and I/O. For example, sending 100 messages in one network round trip is often far faster than sending 100 separate requests.
Priority lanes
Not all tasks are equal. Priority queues let critical jobs, such as account creation or payment confirmation, move ahead of less urgent work, such as analytics aggregation or report generation. This protects important user journeys during busy periods.
Idempotency and deduplication
Queues can deliver the same message more than once. Design tasks to be idempotent so running them twice produces the same result. Use unique identifiers or deduplication keys to avoid repeated side effects.
Sharding by key
When order matters for a specific entity, route related tasks to the same worker or partition. This prevents race conditions while still allowing many workers to run in parallel across different keys.
Operational details that matter
Throughput is not only a code problem. It is also an operations problem. A few details often decide whether a queue-based system stays healthy under load.
- Visibility timeout: If a worker is busy for a long time, the message should not reappear unexpectedly. Tune timeouts to match real task duration.
- Retry policy: Use bounded retries with exponential backoff. Distinguish transient errors from permanent ones.
- Dead-letter queues: Capture tasks that fail repeatedly so they can be inspected and fixed without blocking the main flow.
- Concurrency limits: Set per-worker and per-queue limits to control memory, CPU, and downstream pressure.
- Observability: Track backlog size, task age, processing time, error rate, and retry count. Alert when the backlog grows faster than workers can drain it.
These controls help you keep throughput steady and make performance issues easier to diagnose.
Measuring the right things
To know whether background queues are actually improving speed, measure both system health and user experience. Useful metrics include:
- End-to-end latency: Time from task creation to completion.
- Backlog depth: Number of waiting tasks over time.
- Throughput: Tasks completed per second under different load levels.
- Failure and retry rates: How often tasks fail and how many succeed after retry.
- Resource saturation: CPU, memory, network, and database utilization while workers run.
Pair these with user-facing metrics such as notification delay, export readiness time, and fulfillment latency. The goal is to confirm that deferring work does not create unacceptable waits for the people using the product.
A practical example
Consider a checkout flow that must create an order, reserve inventory, and send a confirmation email. The order creation and inventory reservation need immediate consistency. The email does not. By moving email delivery to a background job, the checkout response stays fast and predictable. During a flash sale, the queue absorbs the surge in emails while workers process them at a sustainable pace. If sending fails, the system retries without blocking purchases.
The same idea applies to data-heavy tasks. A reporting feature can accept a request, place it in a queue, and notify the user when the report is ready. This avoids long-running database queries in the request path and keeps the application responsive.
Common pitfalls
- Treating the queue as a cache: Queues are for work, not for storing unrelated state.
- Ignoring poison tasks: Without dead-letter handling, one bad task can block progress.
- Unbounded concurrency: Running too many workers at once can overload databases or APIs.
- No backoff: Retrying immediately can amplify failures instead of recovering from them.
- Mixed concerns: Putting too many unrelated task types in one queue makes capacity and priority hard to manage.
When queues are not enough
Queues help, but they are not a fix for deeper bottlenecks. If the database is undersized, if downstream services are slow, or if task logic is inefficient, throughput will still be limited. In those cases, combine queue-based processing with schema improvements, indexing, caching, connection pooling, and service-level optimizations.
Conclusion
Queues and background jobs give software a way to handle bursts without sacrificing reliability or responsiveness. They smooth traffic, protect critical paths, and make capacity easier to manage. When paired with careful measurement and operational discipline, this approach is one of the most effective ways to improve throughput while keeping the system calm under pressure.